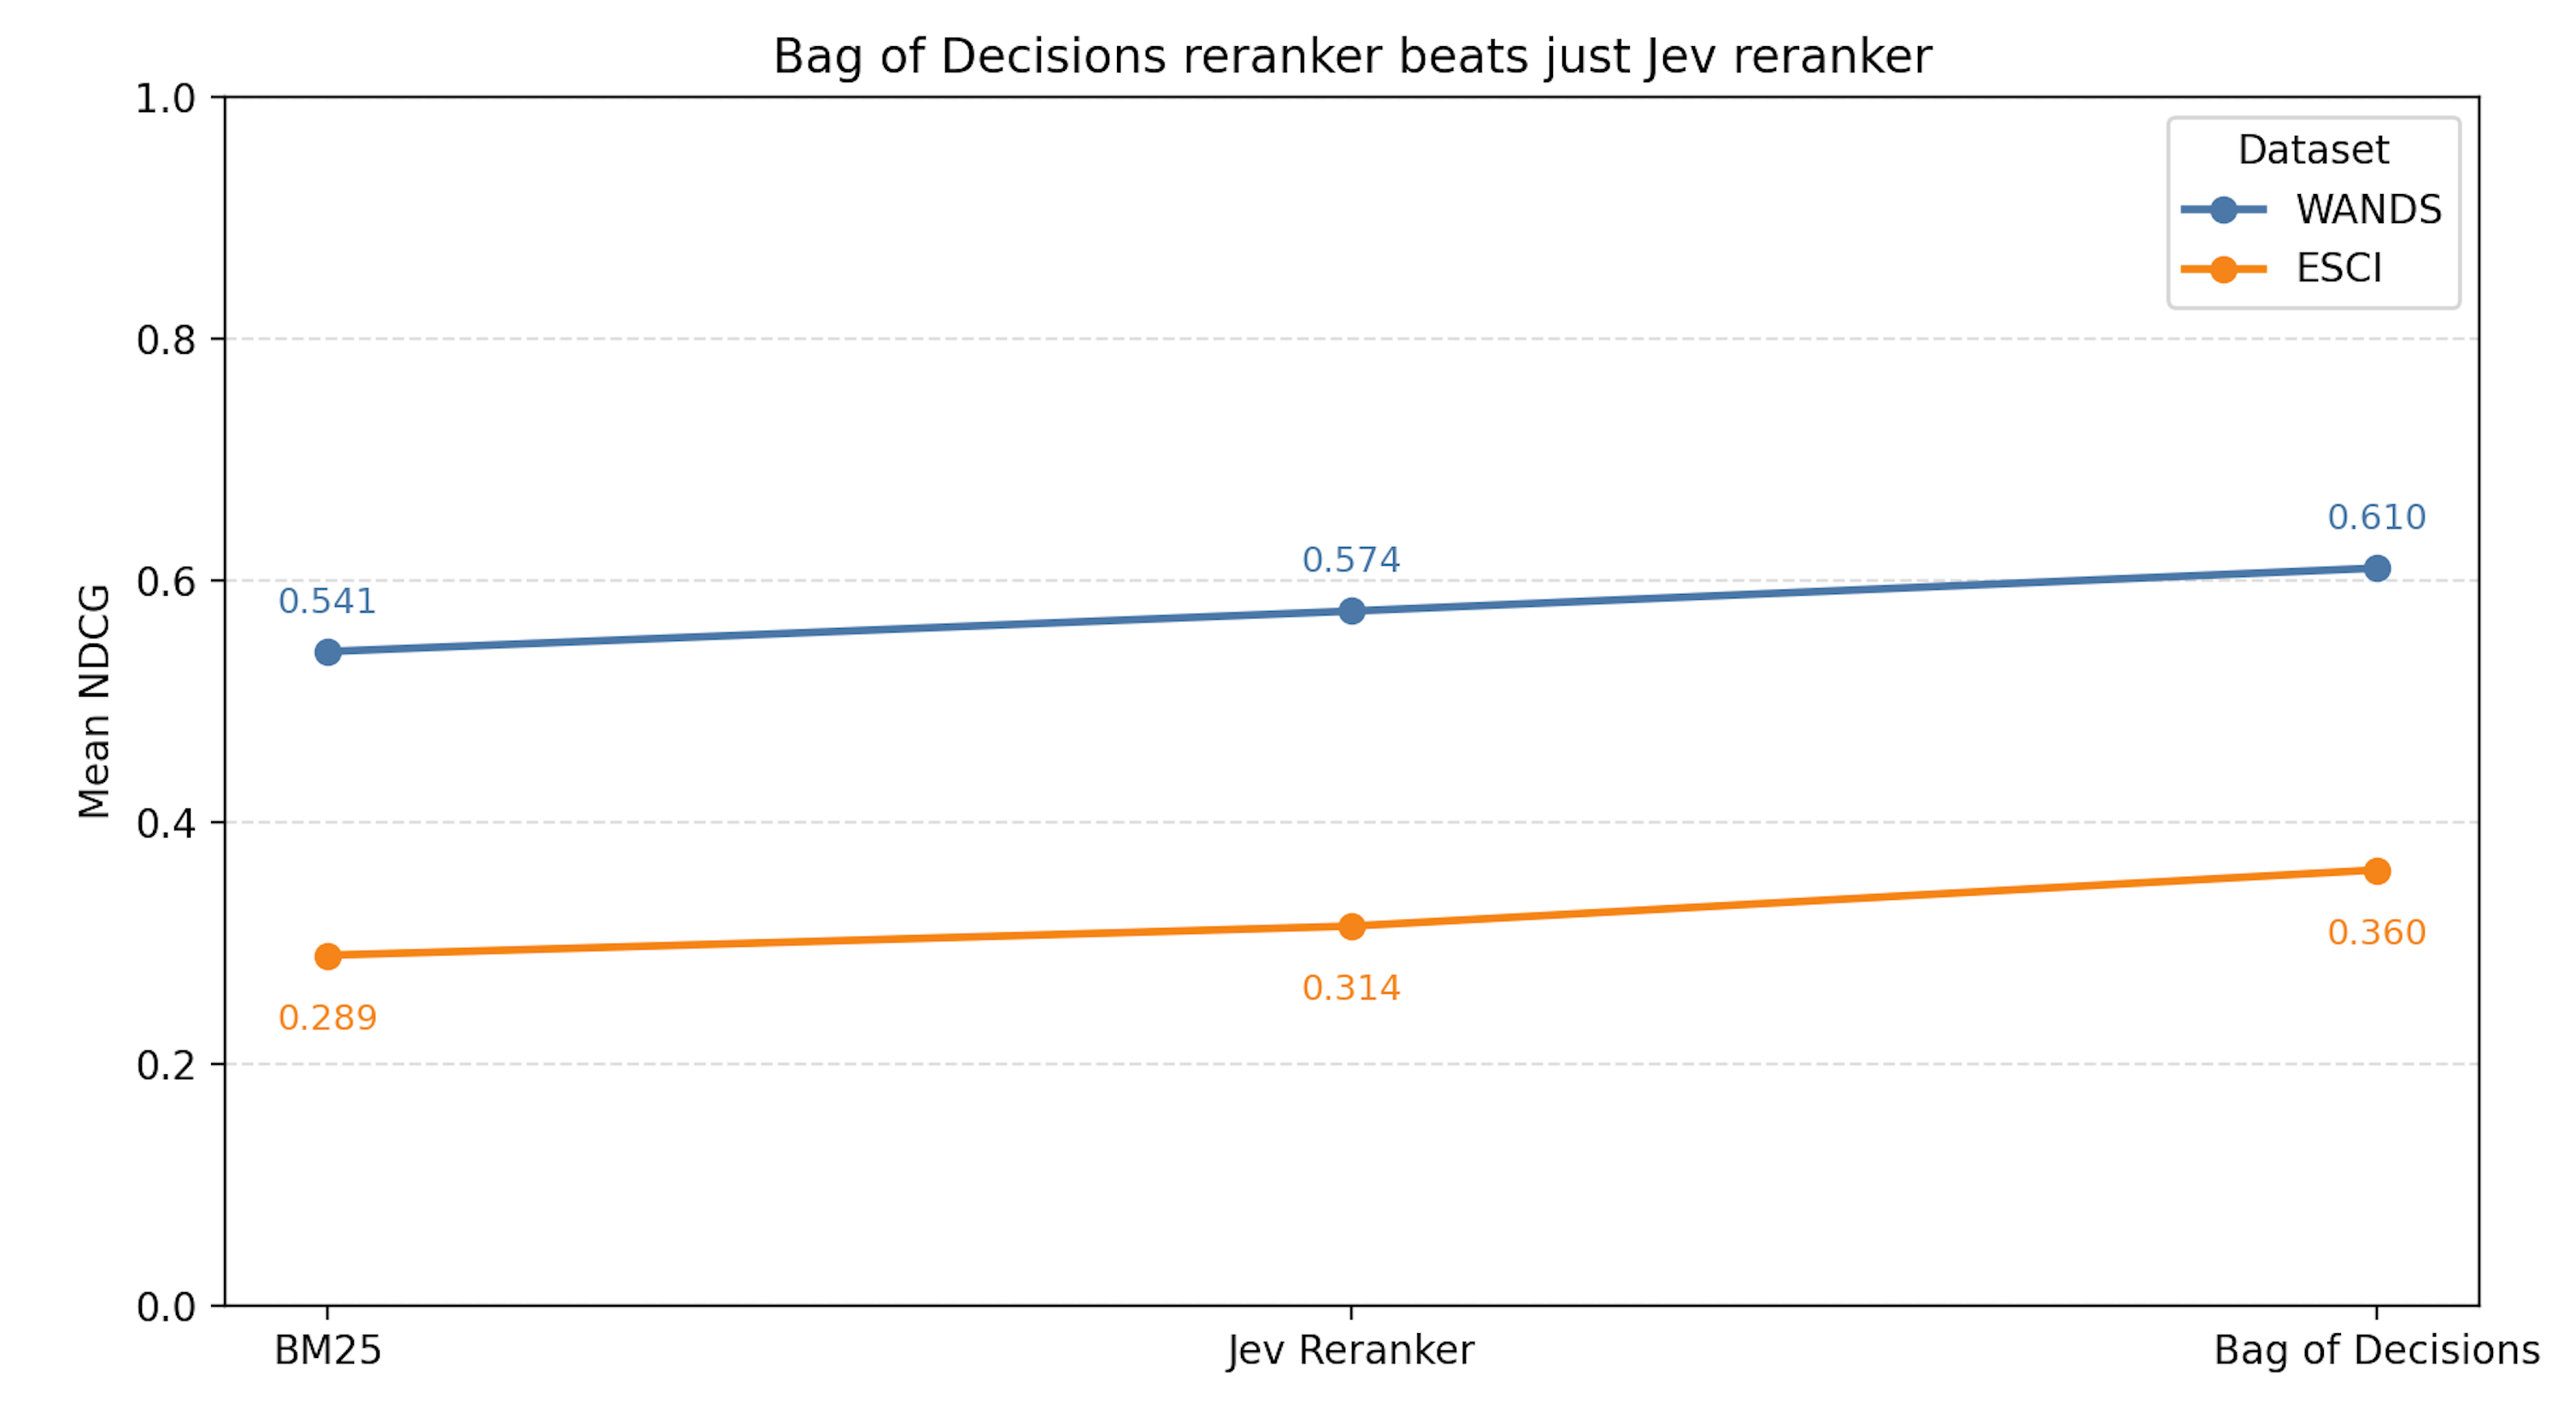
In a Jev reranker you ask Jev to give P(Yes) of the answer to a question like Is this document relevant to the query? And you rank by P(yes) It works! But... that's kinda boring. I think we can do better: we could also have an LLM generate the questions per query. IE query "desk for kids" has us evaluate products with criteria like Is it less than 36 inches? Is it a playful design? Does it explicitly say its designed for children? Then rerank this query using the sum of P(yes) of those...
14 days ago • 1 min read
Hey all, Just a note tomorrow I'll be giving a talk on High-Scale Agent Memory in Turbopuffer Its a first step into a larger world! Agent memory helps new sessions feel like they're continuing a conversation not restarting one. Come, have fun, see the mistakes I've made, and get an intro to Turbopuffer. Event link - https://maven.com/p/e48f16/high-scale-agentic-memory-with-turbopuffer Cheers, -Doug Slack Community * Events · Consulting · Training (use code search-tips) You're subscribed to...
22 days ago • 1 min read
This week the Retrieval Augmented Gathering online conference continues! Last week we explored index-only SPLADE, got a demo of tensors in the search engine, and how to think of agentic memory as telemetry. This week we've got talks below: Embeddings don't solve RAG (today) Solving retrieval for agents isn't as simple as chunk + embed. For one, similarity is not relevance. An decides what's relevant depending on not just raw text, but everything that 'surrounds' it. Places it in context....
25 days ago • 1 min read
I've spent the last several years building query classifiers with LLMs. Now Jev has arrived, making this process simpler, faster, and more accurate. I decided to sit down with a simple query understanding task with Jev. It let me make better tradeoffs in recall / precision, while being an order of magnitude faster / cheaper Enjoy: https://softwaredoug.com/blog/2026/09/22/jev-query-understanding.html -Doug Slack Community * Events · Consulting · Training (use code search-tips) You're...
30 days ago • 1 min read
Friday we had a search career Q&A with Brian Pedersen. Recap notes can be found here. Then, we're continuing on with Retrieval Augmented Gathering on Tuesday! What's on deck: Tuesday: Neural search without query-time latency - can we do SPLADE without spinning up a query time inference service w/ GPUs etc by just precomputing at index-time? Kumar Shivendu of QDrant will help us find out Wednesday: Vespa's killer feature: tensors in the search engine. What are tensors? Why does that matter?...
about 1 month ago • 1 min read
Hey all, Many people may have seen Brian Pedersen share a report from his firm on search hiring team statistics. So what should you, a search professional, take out from Brian's data? I wrote my own blog post reflecting on the implications for those of us working in Information Retrieval, and how to prepare ourselves for the agentic era: https://softwaredoug.com/blog/2026/09/17/state-of-search-career Of course, if this interests you, I'll be speaking with Brian tomorrow with a search career...
about 1 month ago • 1 min read
My work is split between mature search teams and new AI teams. Search teams are often farther along and manage a mature, traditional search product. AI teams, however, often don't know what they don't know yet. They've just been cobbled together, have built a few agent demos, and are often in the process of discovering the three big mistakes I blog here: Evals+measurement need to dominate a lot of your product thinking Retrieval isn't "one thing" (ie classic RAG) - its extremely custom to...
about 2 months ago • 1 min read
I'm writing about the weak spots in vector databases. Where you should prod and poke when selecting a vendor. Today: Updating Vector Databases If you think about the old vector search regime, it involved Indexing everything up front Never updating the index Search-only We overindexed on this paradigm, creating data structures focused on good search performance that couldn't tolerate updates. I wrote about how sensitive graph-based vector DBs in particular are to updates, picking on Lucene...
about 2 months ago • 1 min read
Hey all, I wrote a new article about a technique that has come up over and over in my work, especially in my Cheat at Search training, for doing effective query understanding into a large vocabulary. Instead of asking an LLM to classify into a vocabulary. Ask it to hallucinate fake entities, then resolve those to real ones client side. Save yourself a lot of tokens and use cheaper models. https://softwaredoug.com/blog/2026/08/10/hypothetical-classifications -Doug PS - A reminder that Vectors...
2 months ago • 1 min read